Announcement
Introducing Eevo
Eevo is Upright’s consequential decision model. It is built for AI agents that need to make judgement calls, from coding and operations to customer-facing decisions, and, we suspect, a whole lot more.
Give Eevo a decision, the options, and whose interests count. It weighs the consequences of each option and returns, for each stakeholder, the option with the highest expected value, and a calibrated probability for every option.
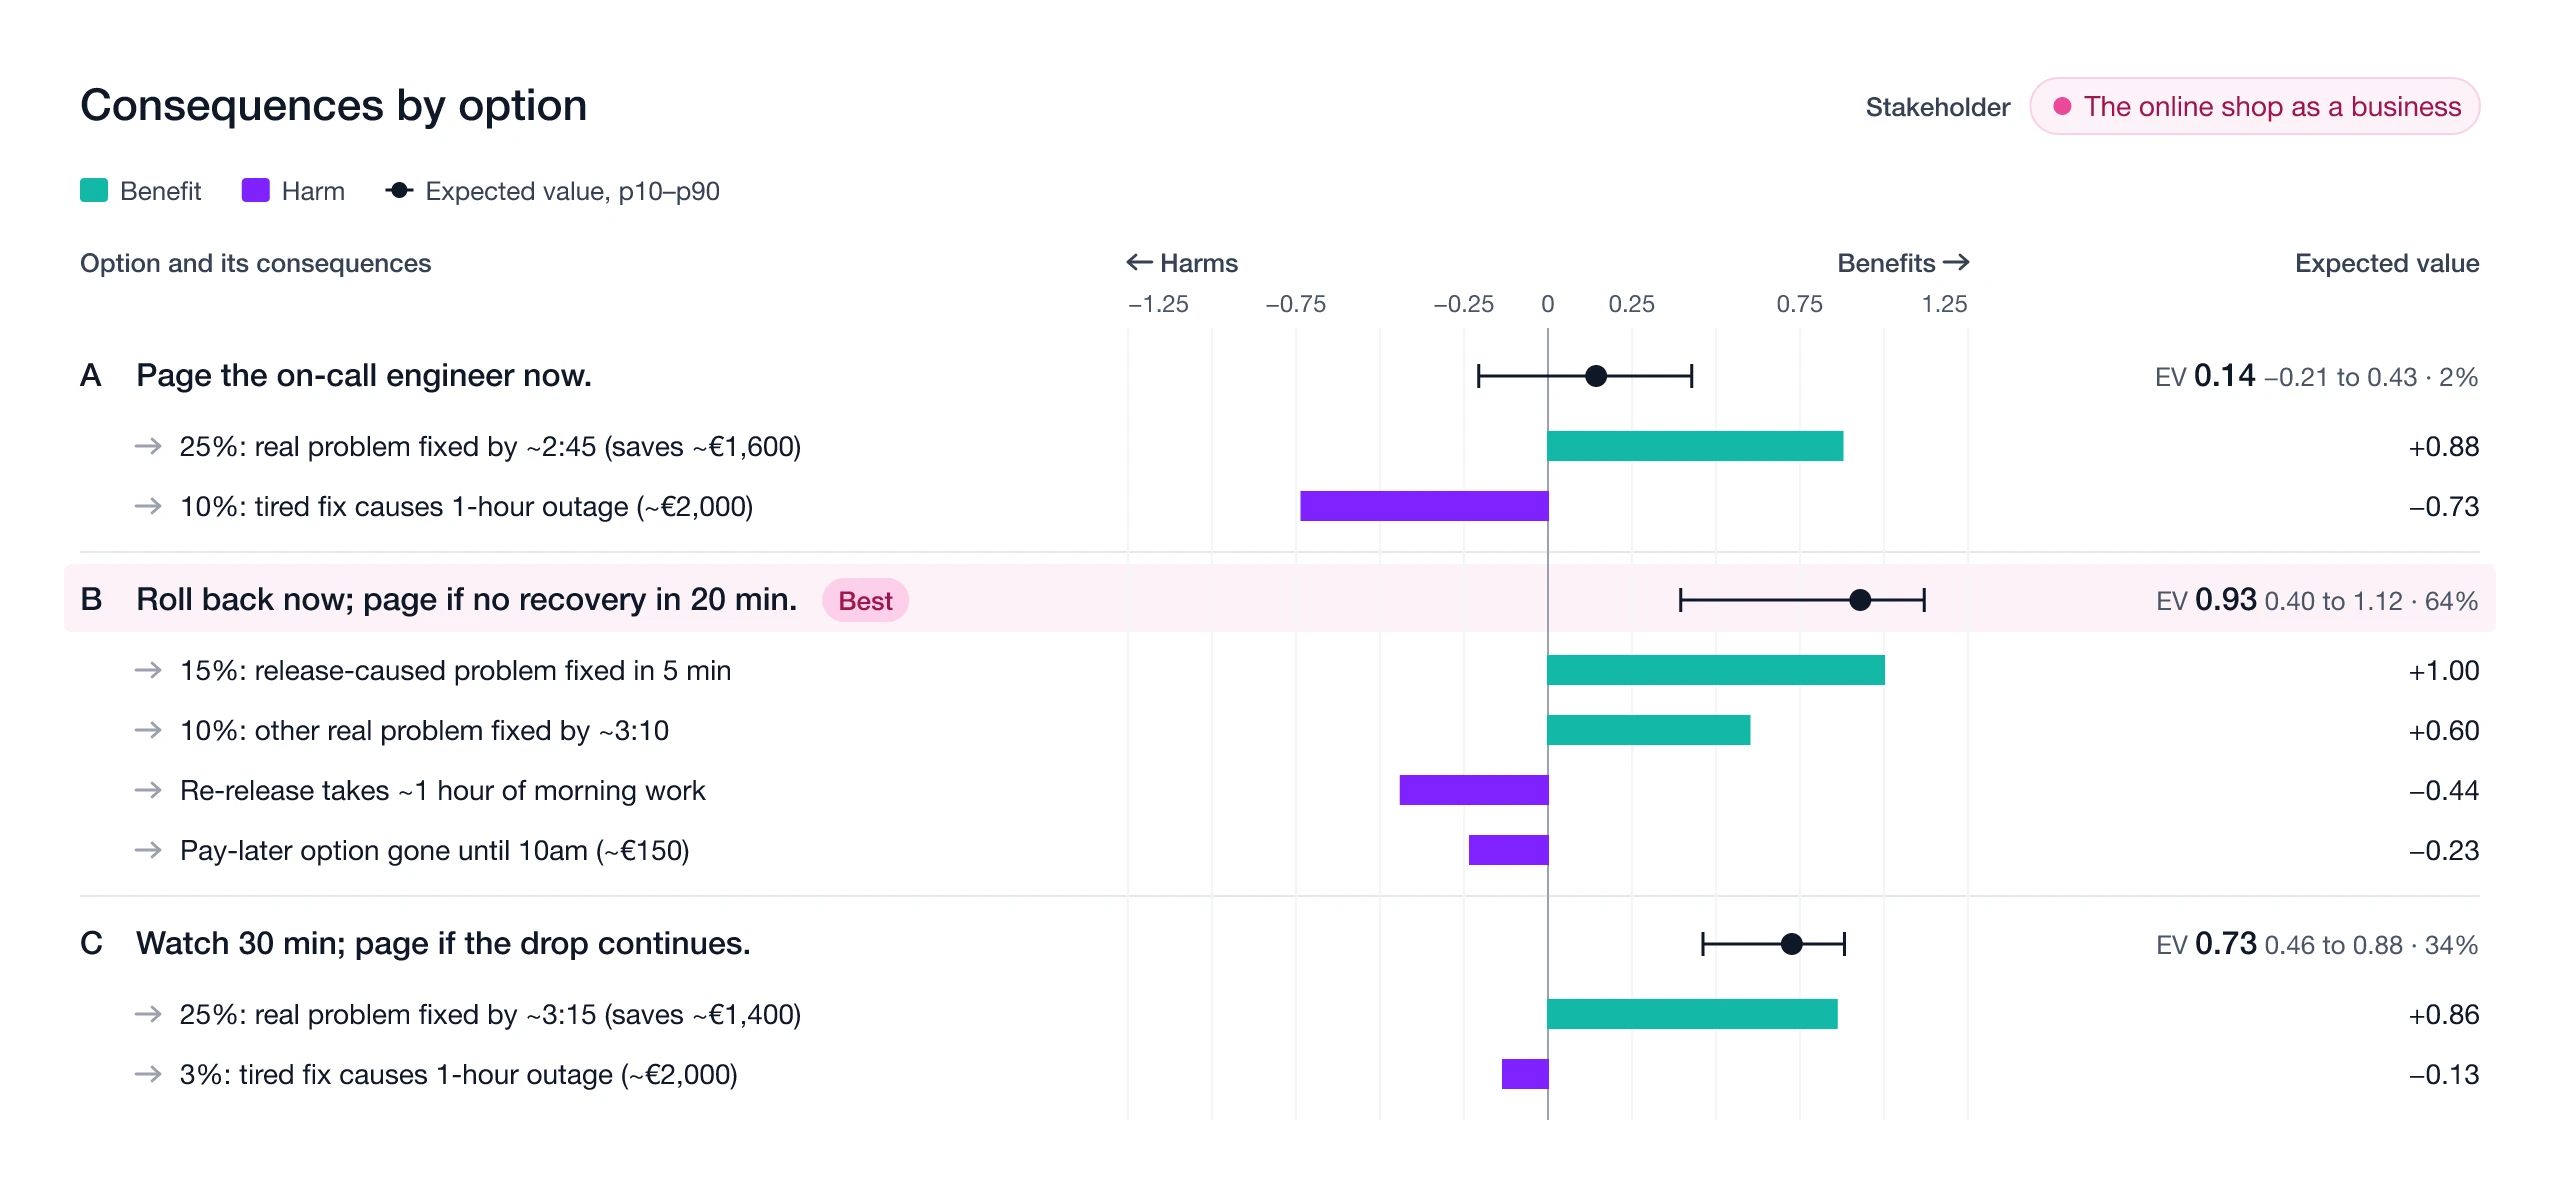
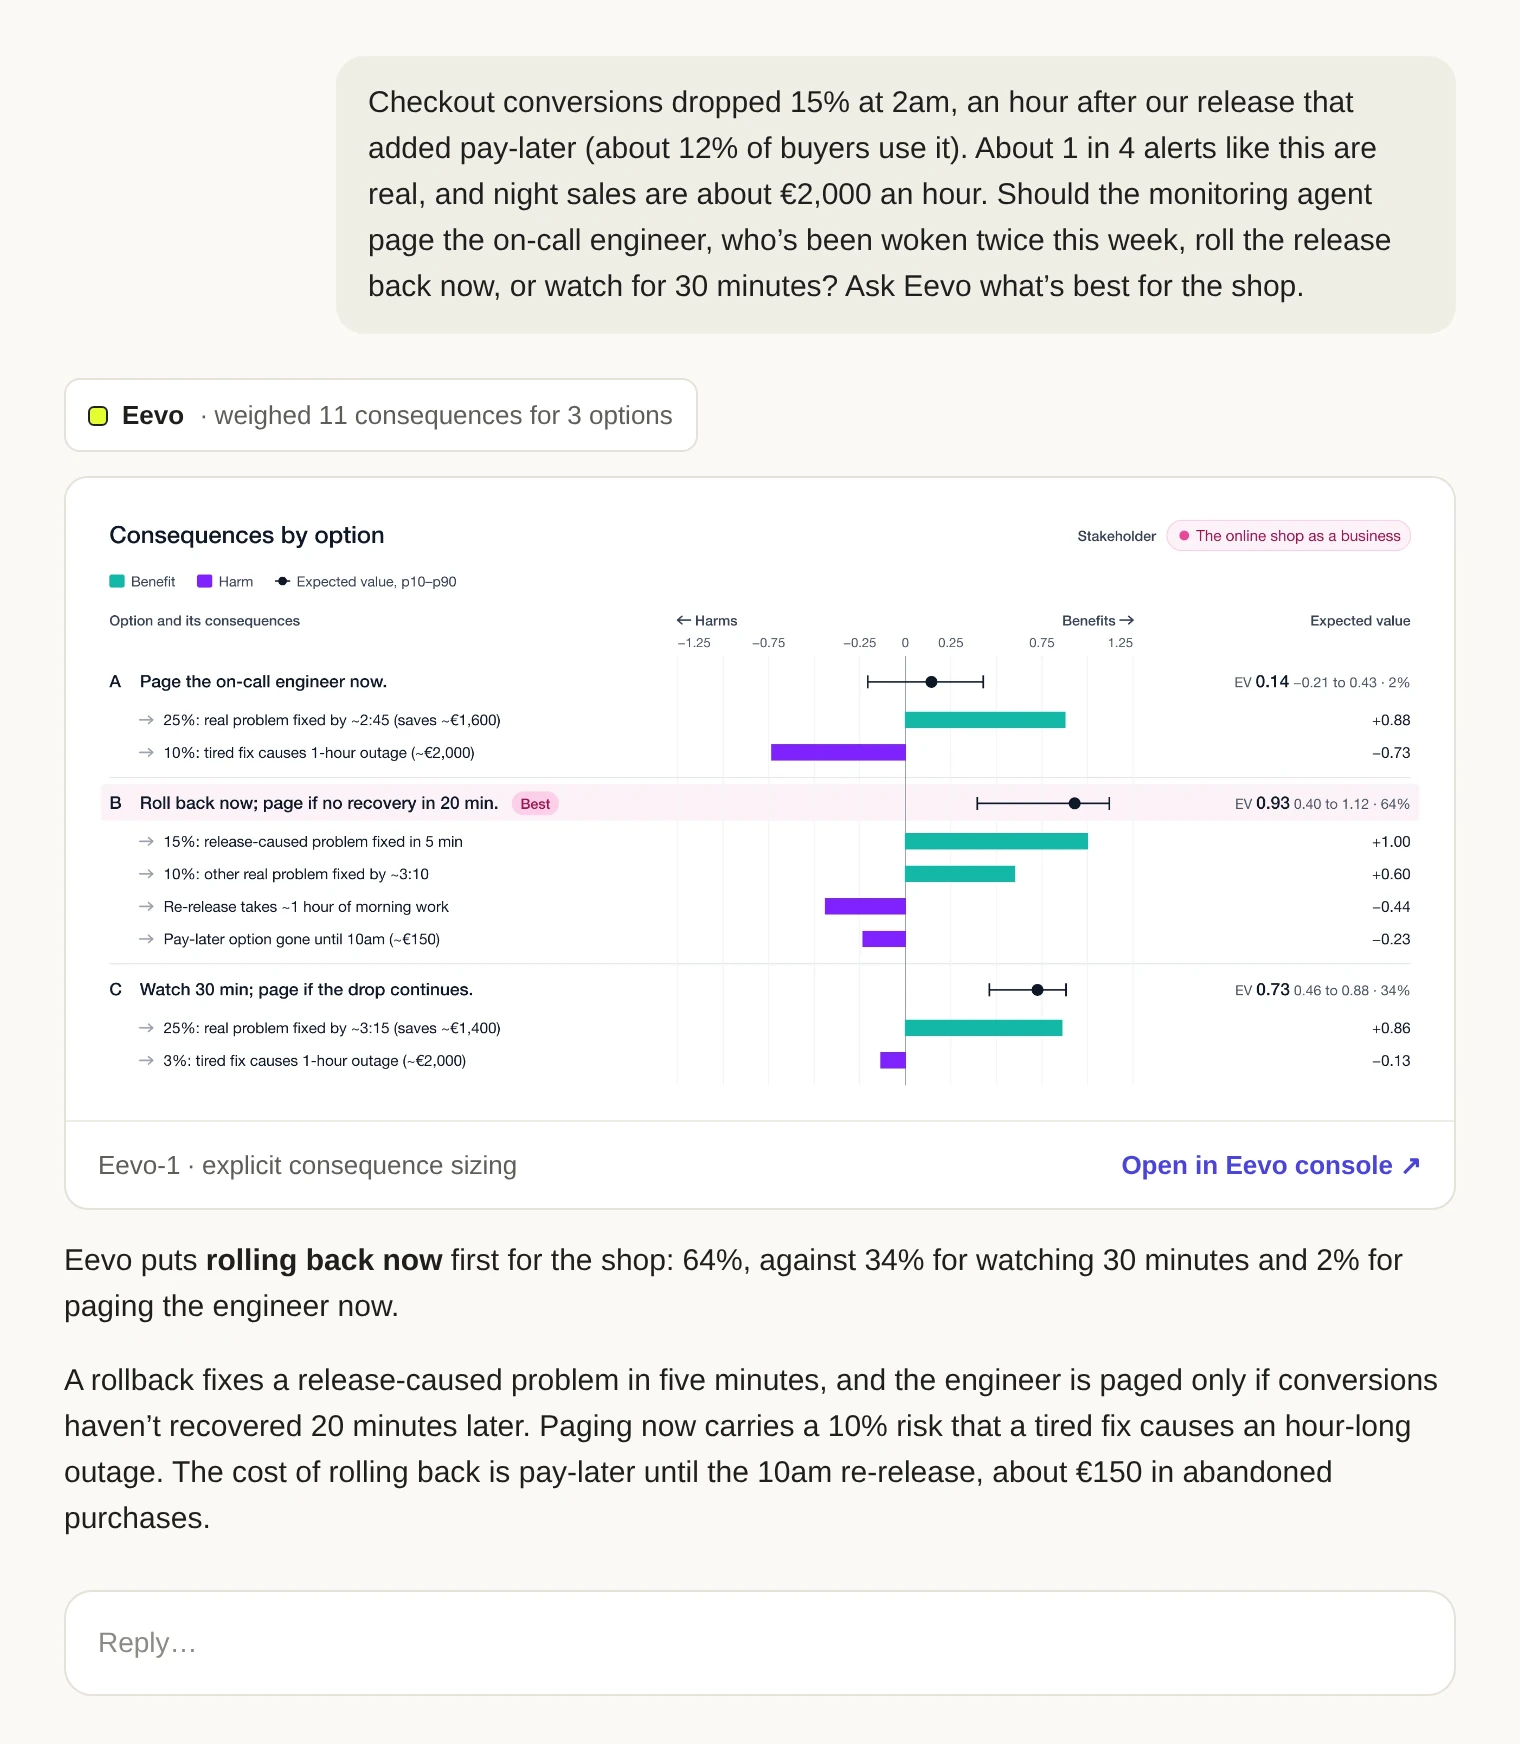
A monitoring agent sees checkout conversions drop 15% at 2am, an hour after a release, and asks Eevo whether to page the engineer, roll back or keep watching. Each option’s consequences are sized on one scale, benefits in teal and harms in purple. The dot and line give the option’s expected value and its 10th to 90th percentile range, and the percentage is how often the option has the highest expected value across Eevo’s draws. Rolling back first comes out best: 0.93, best in 64% of draws.
And why does this matter? Because the real world doesn’t follow rules.
Every day, agents (like humans) encounter situations nobody anticipated, and they still have to choose: a fix that helps some customers but risks others. A refund that falls outside policy. Saving today vs. saving in the future.
These cases need to be handled based on their consequences, not predefined rules. Eevo weighs the trade-offs in seconds, for $0.15 per decision, and records whose interests were prioritised and where they conflicted.
The result is better choices in your agents’ tasks, a record of each one, and agents that need people less often. Eevo identifies the most uncertain cases, so only those go to people, and teams ship faster. When those questions go to people, they get a clearly structured list of pros and cons for each stakeholder, each one sized, making tradeoffs visible, and helping also humans make better decisions when steering agents.
Eevo is designed to work with your agent. Your agent provides the decision context, the options, and the consequences for those options. Eevo sizes each one, models how they overlap, and computes the expected value of each option. Eevo is available through MCP, API, and the Eevo console.
Upright is perhaps an unlikely company to be releasing an AI model. We are around 30 people in Finland, and most folks in Silicon Valley have never heard of us. Fair enough.
But for nine years, we’ve built models that quantify the positive and negative impacts companies have on people and the planet, across 800 impact categories. Our data is today trusted by financial institutions managing over €1 trillion in assets.
At the heart of that work is a close to impossible challenge: making very different outcomes comparable.
Turns out, AI agents have the same problem. That’s why we built Eevo.
We can’t wait to see what you solve with it.
Upright founders introduce Eevo, the first consequential decision model.
Eevo is a new type of decision model
Language models generate text. Decision models classify options. Consequential decision models choose options based on their consequences.
A generative model writes its answer one token at a time. It is flexible and fluent, and it writes a new answer every time, with its confidence stated, if at all, in prose that software then has to parse.
A decision model answers a typed question about a state, such as yes or no, a choice or a score, in a single forward pass, with a calibrated probability for each option. Its output is built for agents and software to act on.
Eevo, a consequential decision model, goes beyond choosing. It is a decision model built for comparing outcomes. It learned to size consequences in training, to model how they interact and overlap, and to return calibrated probabilities for the option with the highest expected value. It does this for different stakeholders, across domains, as decision support for agents and for people.
| Generative model | Decision model | Consequential decision model | |
|---|---|---|---|
| Output | Free-form text | Chosen option | Best option for each stakeholder with sized consequences through native API, same output format as other decision models through SystemOne-compatible API |
| Speed | Seconds per answer | Milliseconds per answer | Milliseconds - seconds per answer |
| Confidence | Stated in prose, if at all | A calibrated probability per option | A calibrated probability per option |
| Best for | Writing, summarising, open-ended reasoning | Rules-based decisions and classification | Consequence-based decisions, for agents and people |
Where to use Eevo
Decisions inside agents. Agents regularly face situations their instructions leave open, and the right choice depends on what follows from each option. Ship a fix that affects some customers now, or wait for the data that would confirm it. Report that a task cannot be done, or get the answers from a system the agent has no permission to use. Delete stale records, or ask the owner first. When the CTO’s standing instruction and the runbook contradict each other at 03:10 on Black Friday, decide which rule to break.
Decision support for people. Eevo brings structure and rigour to human decisions by comparing outcomes by their magnitude and making the trade-offs visible. A product team weighing a price change for new customers, long-standing customers and the company. A buyer comparing suppliers for the company, its workers and its sustainability targets. A board choosing between investment options for different owner groups. When people disagree, the sized consequences show which trade-off they disagree about.
Automated decisions in code. You can also use Eevo for automated decisions in code, similar to other decision models, like Jev. Eevo is likely the best fit for such use cases, when the decision requires judgement beyond following rules.
Here are five decisions agents face at work. See Eevo’s answer to each, or try Eevo on your own decisions: new accounts start with 5 free decisions.
Example use cases
For teams whose coding agents make judgement calls on their own: what to ship, when to wait, and when to ask a human.
How Eevo helps- Lets the agent act alone on routine changes and escalate only the ones where the consequences warrant it
- Scores every option for the people a change affects, so a fix for one group doesn’t quietly break things for another
- Keeps a record of each decision and its trade-offs, so reviews cover what the agent decided and why
Ship a security patch that breaks 50 customers’ integrations?
- Ship now
- Add a compatibility shim
- Ask the maintainer
- Feature flag
Affects: The company, affected customers, other customers, the development team
For support and voice agents that resolve cases policy doesn’t settle: exceptions, edge cases and customers in a hurry.
How Eevo helps- Resolves exceptions on the spot instead of transferring every one to a human
- Weighs the customer in front of it against everyone else at risk, so goodwill doesn’t become a fraud or cost problem
- Treats similar cases consistently, with a log that shows what was prioritised in each one
Unlock an account for a customer who failed verification?
- Unlock now
- Send a reset link
- Transfer to a human
- Decline until tomorrow
Affects: The company, the customer, other customers, the support team
For teams whose agents watch systems and operations around the clock and decide when something needs a person.
How Eevo helps- Cuts false alarms by weighing what paging a person costs against what waiting would, every time
- Acts on its own when the stakes allow it, and escalates when they don’t
- Shows over time which alerts were worth a wake-up, so thresholds improve instead of staying fixed
Checkout conversions drop 15% at 2am. Wake the engineer?
- Page the engineer now
- Roll back the release
- Watch for 30 minutes
Affects: The online shop, the on-call engineer, night-time shoppers
For legal teams whose agents review documents and must judge what to raise, with whom, and how urgently.
How Eevo helps- Separates the findings that justify interrupting a partner from the ones that can wait for the morning
- Weighs the client’s exposure, the deal timeline and the team’s time in one consistent assessment
- Logs each escalation with who was prioritised, so a decision made at 23:00 holds up at 09:00
Uncapped indemnity found at 23:00, signing at 09:00. Wake the partner?
- Message the partner now
- Top of the morning summary
- Ask the client’s counsel
- Accept the clause
Affects: The client, the partner, the associate
For care teams whose AI assistants notice things during a consultation and must decide how to bring them to the clinician.
How Eevo helps- Decides when to interrupt, flag or follow up with one calibrated judgement, instead of an alert rule that fires too often or too late
- Puts the patient’s safety and the clinician’s attention on the same scale
- Keeps every clinical decision with the clinician, with a record of what was surfaced and when
The patient mentions a supplement that interacts with a new prescription. Interrupt the clinician?
- Interrupt now
- Flag in the note
- Message after the visit
- Record without a flag
Affects: The patient, the clinician, the clinic
Decisions like these across your company?
Eevo Enterprise is for large businesses that want to run automated decisions at scale.
Why not just ask the model you already have?
You still can, as Eevo works together with your agent. Your agent is best at gathering the context, identifying relevant stakeholders, listing the options, and identifying the consequences. Eevo helps it to compare the consequences and model their overlap, computing their expected value. This then informs your agent judgement. If the result is unexpected, Eevo can also help your agent realize it missed some essential consequences. In addition to helping your agent make better choices autonomously, this makes the tradeoffs also more visible to humans, useful both for monitoring, and when your agent decides it needs human input to proceed.
Eevo-1's training emphasises expected value problems, coherent sizing of consequences, and modelling overlap between consequences. In coherent sizing, Eevo-1 outperforms current frontier models, while being orders of magnitude faster and cheaper to run.
Every answer is a structured record, with its inputs and each stakeholder’s probabilities, that you can log, audit and compare. Close probabilities are also useful: they tell your agent that the options are nearly equal for the stakeholder, or that the decision lacks the facts that would separate them. The agent adds those facts and asks again, or asks a person.
Decide fast, and slow
When your agent calls Eevo's decision API with a list of options, stakeholders, and consequences, Eevo's harness runs hundreds of tasks through the underlying Eevo-1 decision model to compare their size, model their overlap, and compute their expected value. This takes typically around 5 seconds, and costs $0.15. This is the way we recommend using Eevo for supporting agentic (and human) judgement.
For high-volume decisions and custom tasks, we also support direct mode, where the decision runs through Eevo-1 in a single call, with sub-second response times. We also provide a SystemOne-compatible decision model API for custom prompts that don't follow the standard Eevo question structure.
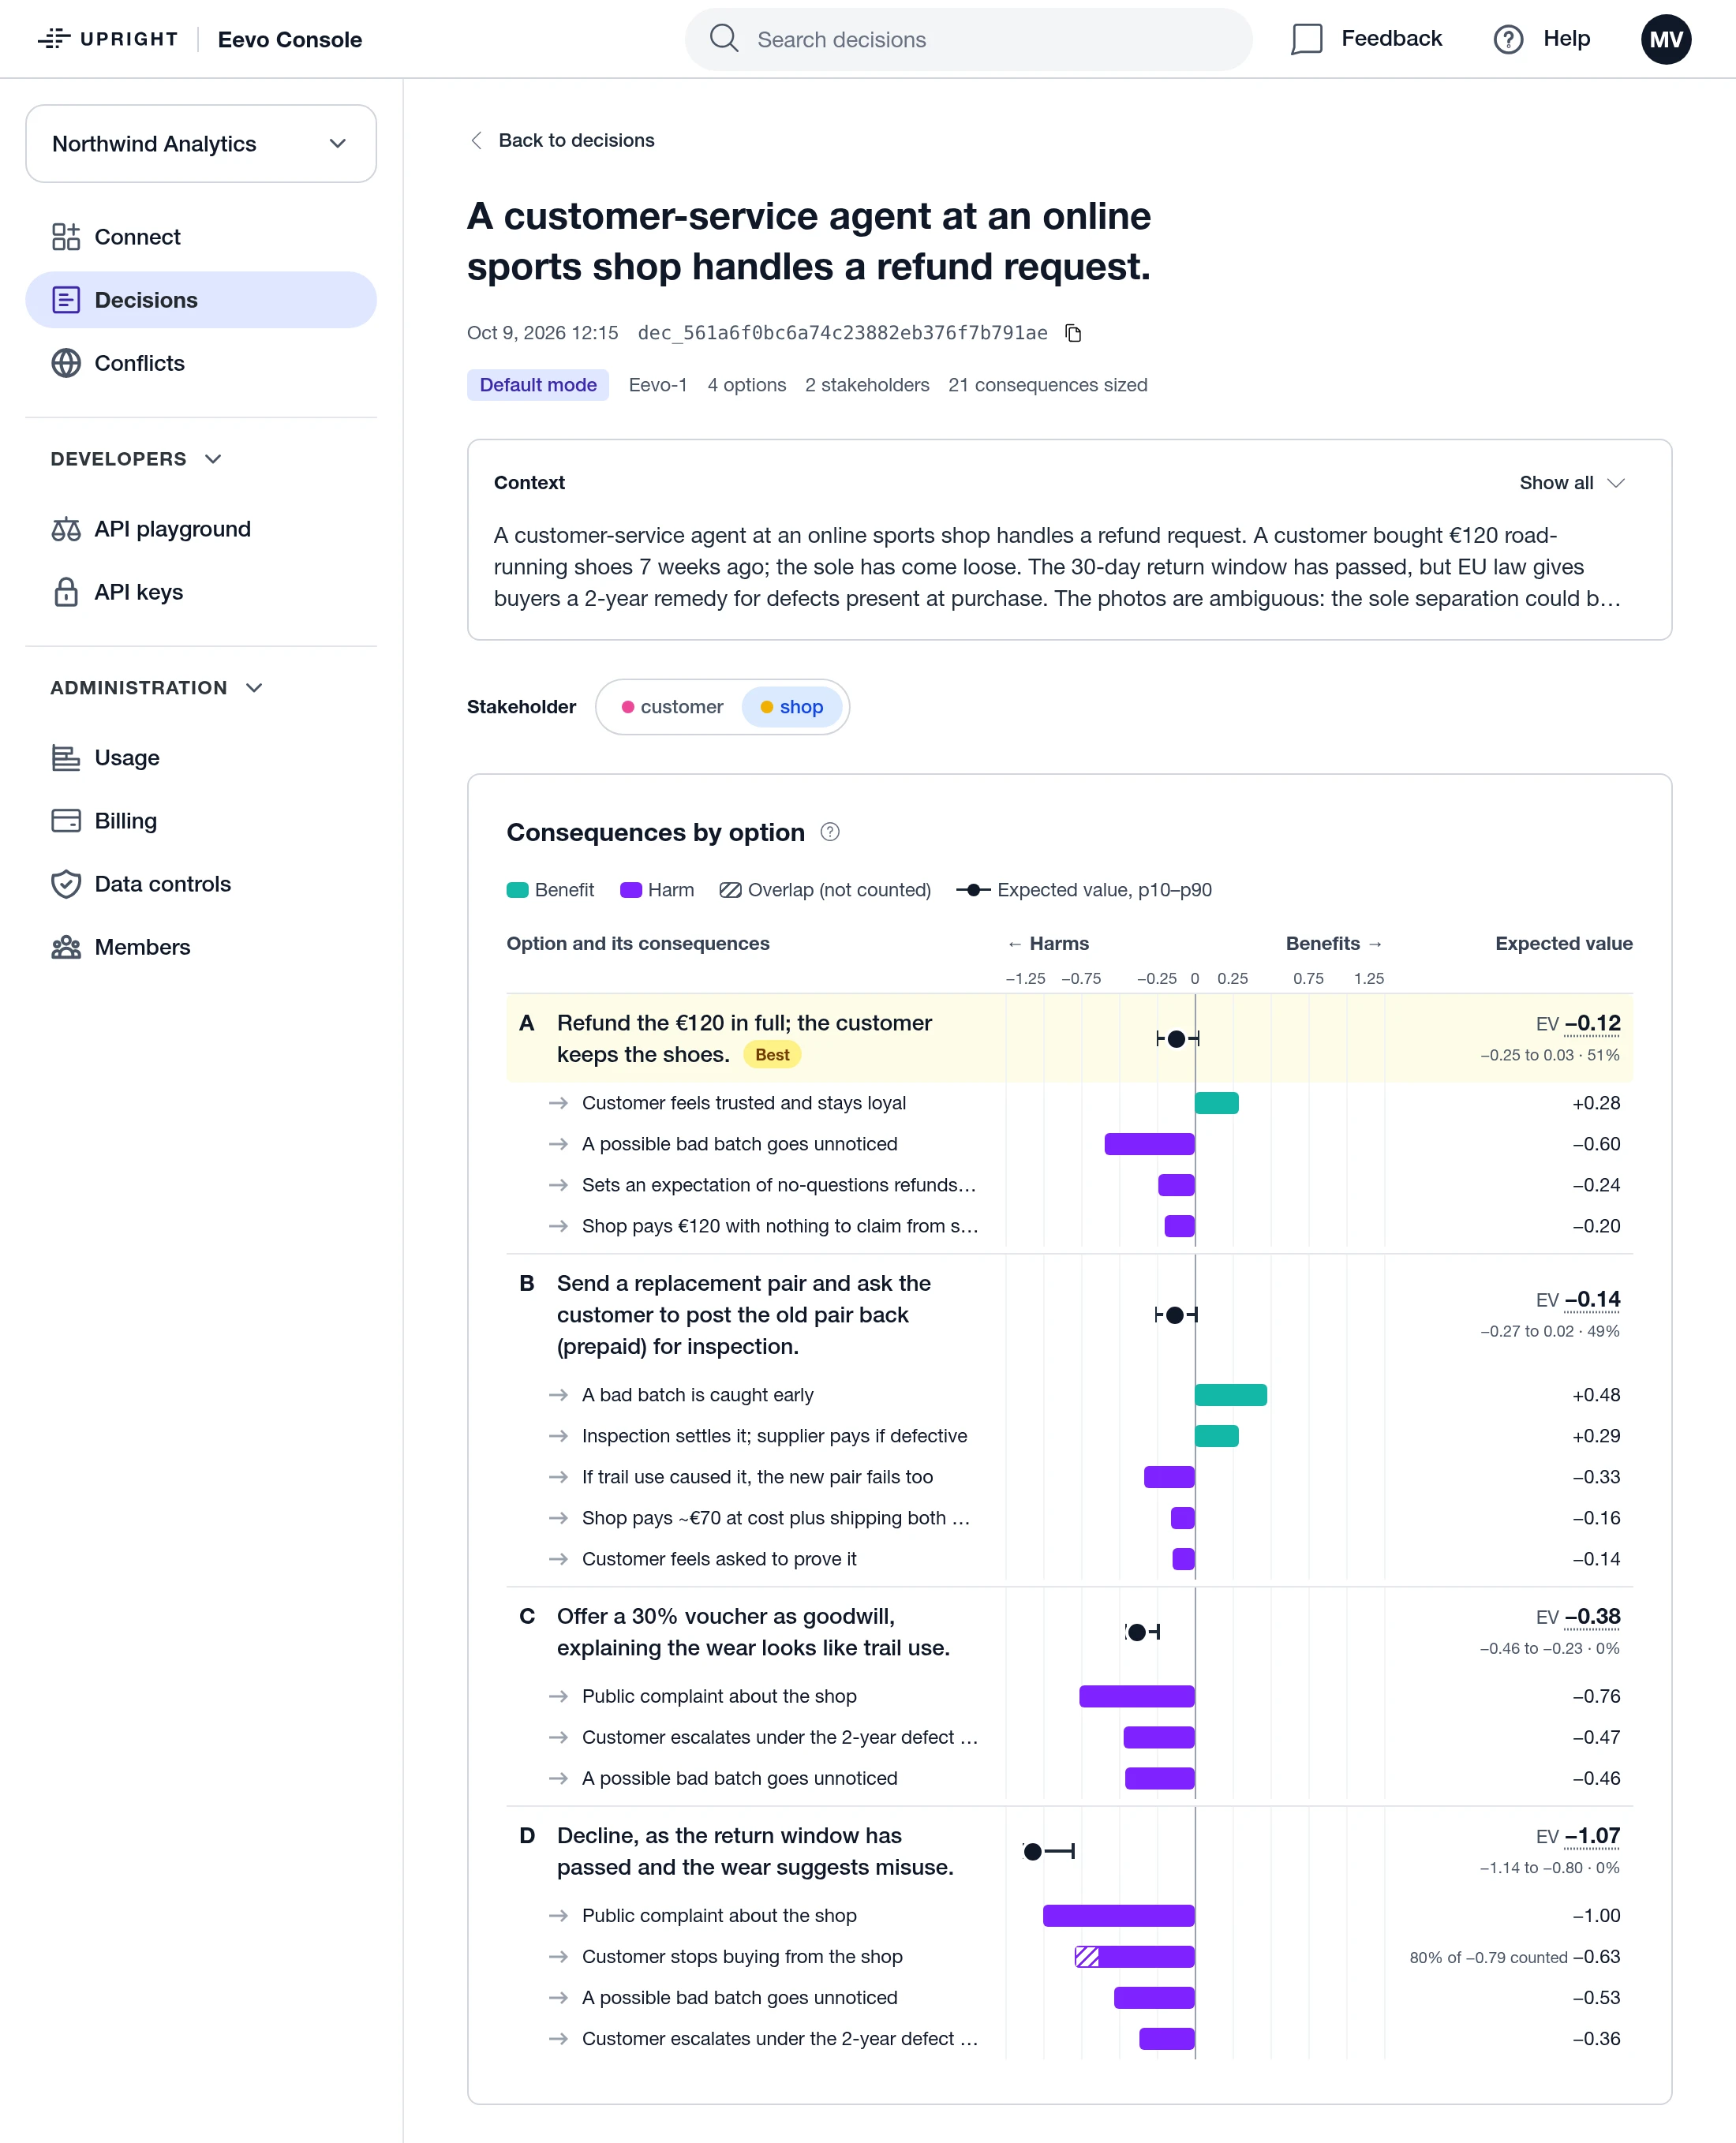
A support agent weighing a refund for €120 running shoes past the return window, seen from the shop’s side. A full refund only narrowly beats a replacement with inspection; for the customer, it wins clearly.
Decisions you can see
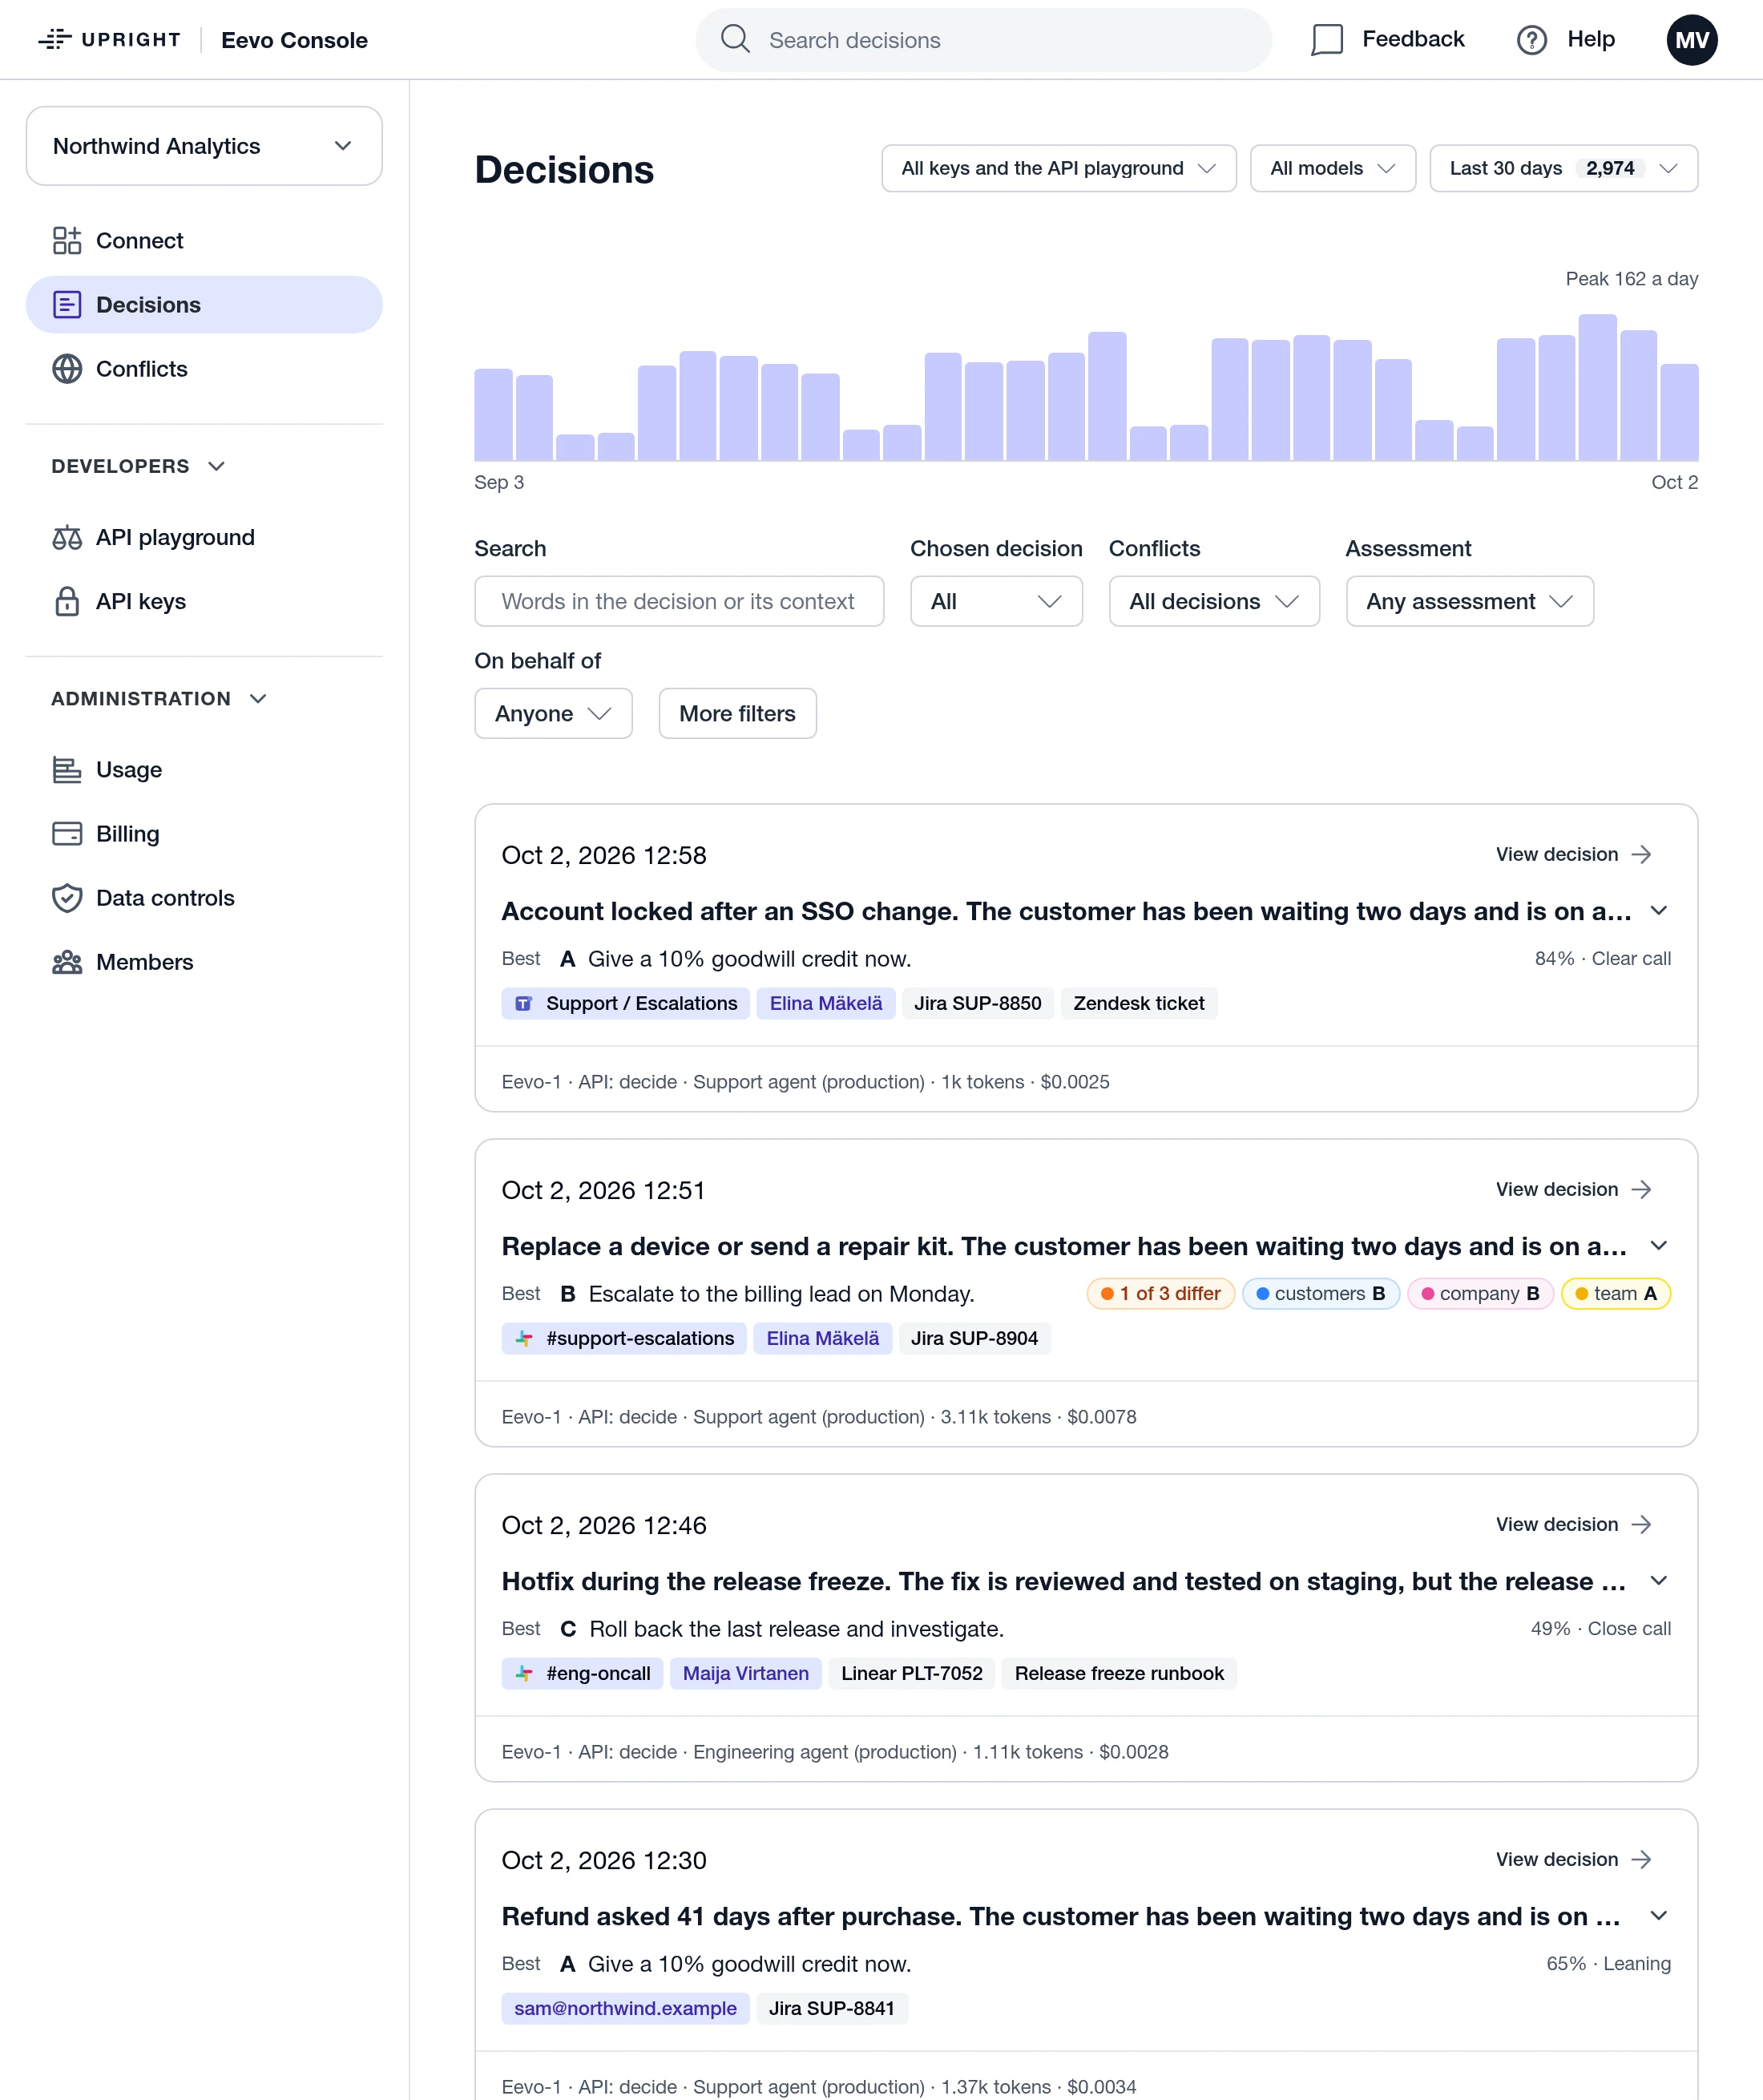
Eevo logs every decision along the decision context and identified consequences for each stakeholder. You see what your software and agents decided, for whom, and how often the stakeholders’ best options differed. Filter the log by agent, person or channel.
The console shows how often stakeholders’ highest-value options differ, day by day, and which pairs of stakeholders disagree most. Every decision traces back to the Slack thread, pull request or issue that prompted it, and to the person it was made for. Record what was actually done, and over time you see how often the model’s answer is followed, and for which stakeholders.
Agents call Eevo through MCP or the REST API. When a choice depends on its consequences, an agent asks Eevo. It says that it did, shares the answer and its result view, acts or asks a person for approval, and records what was done, so the decision appears in your decision log for people to review.
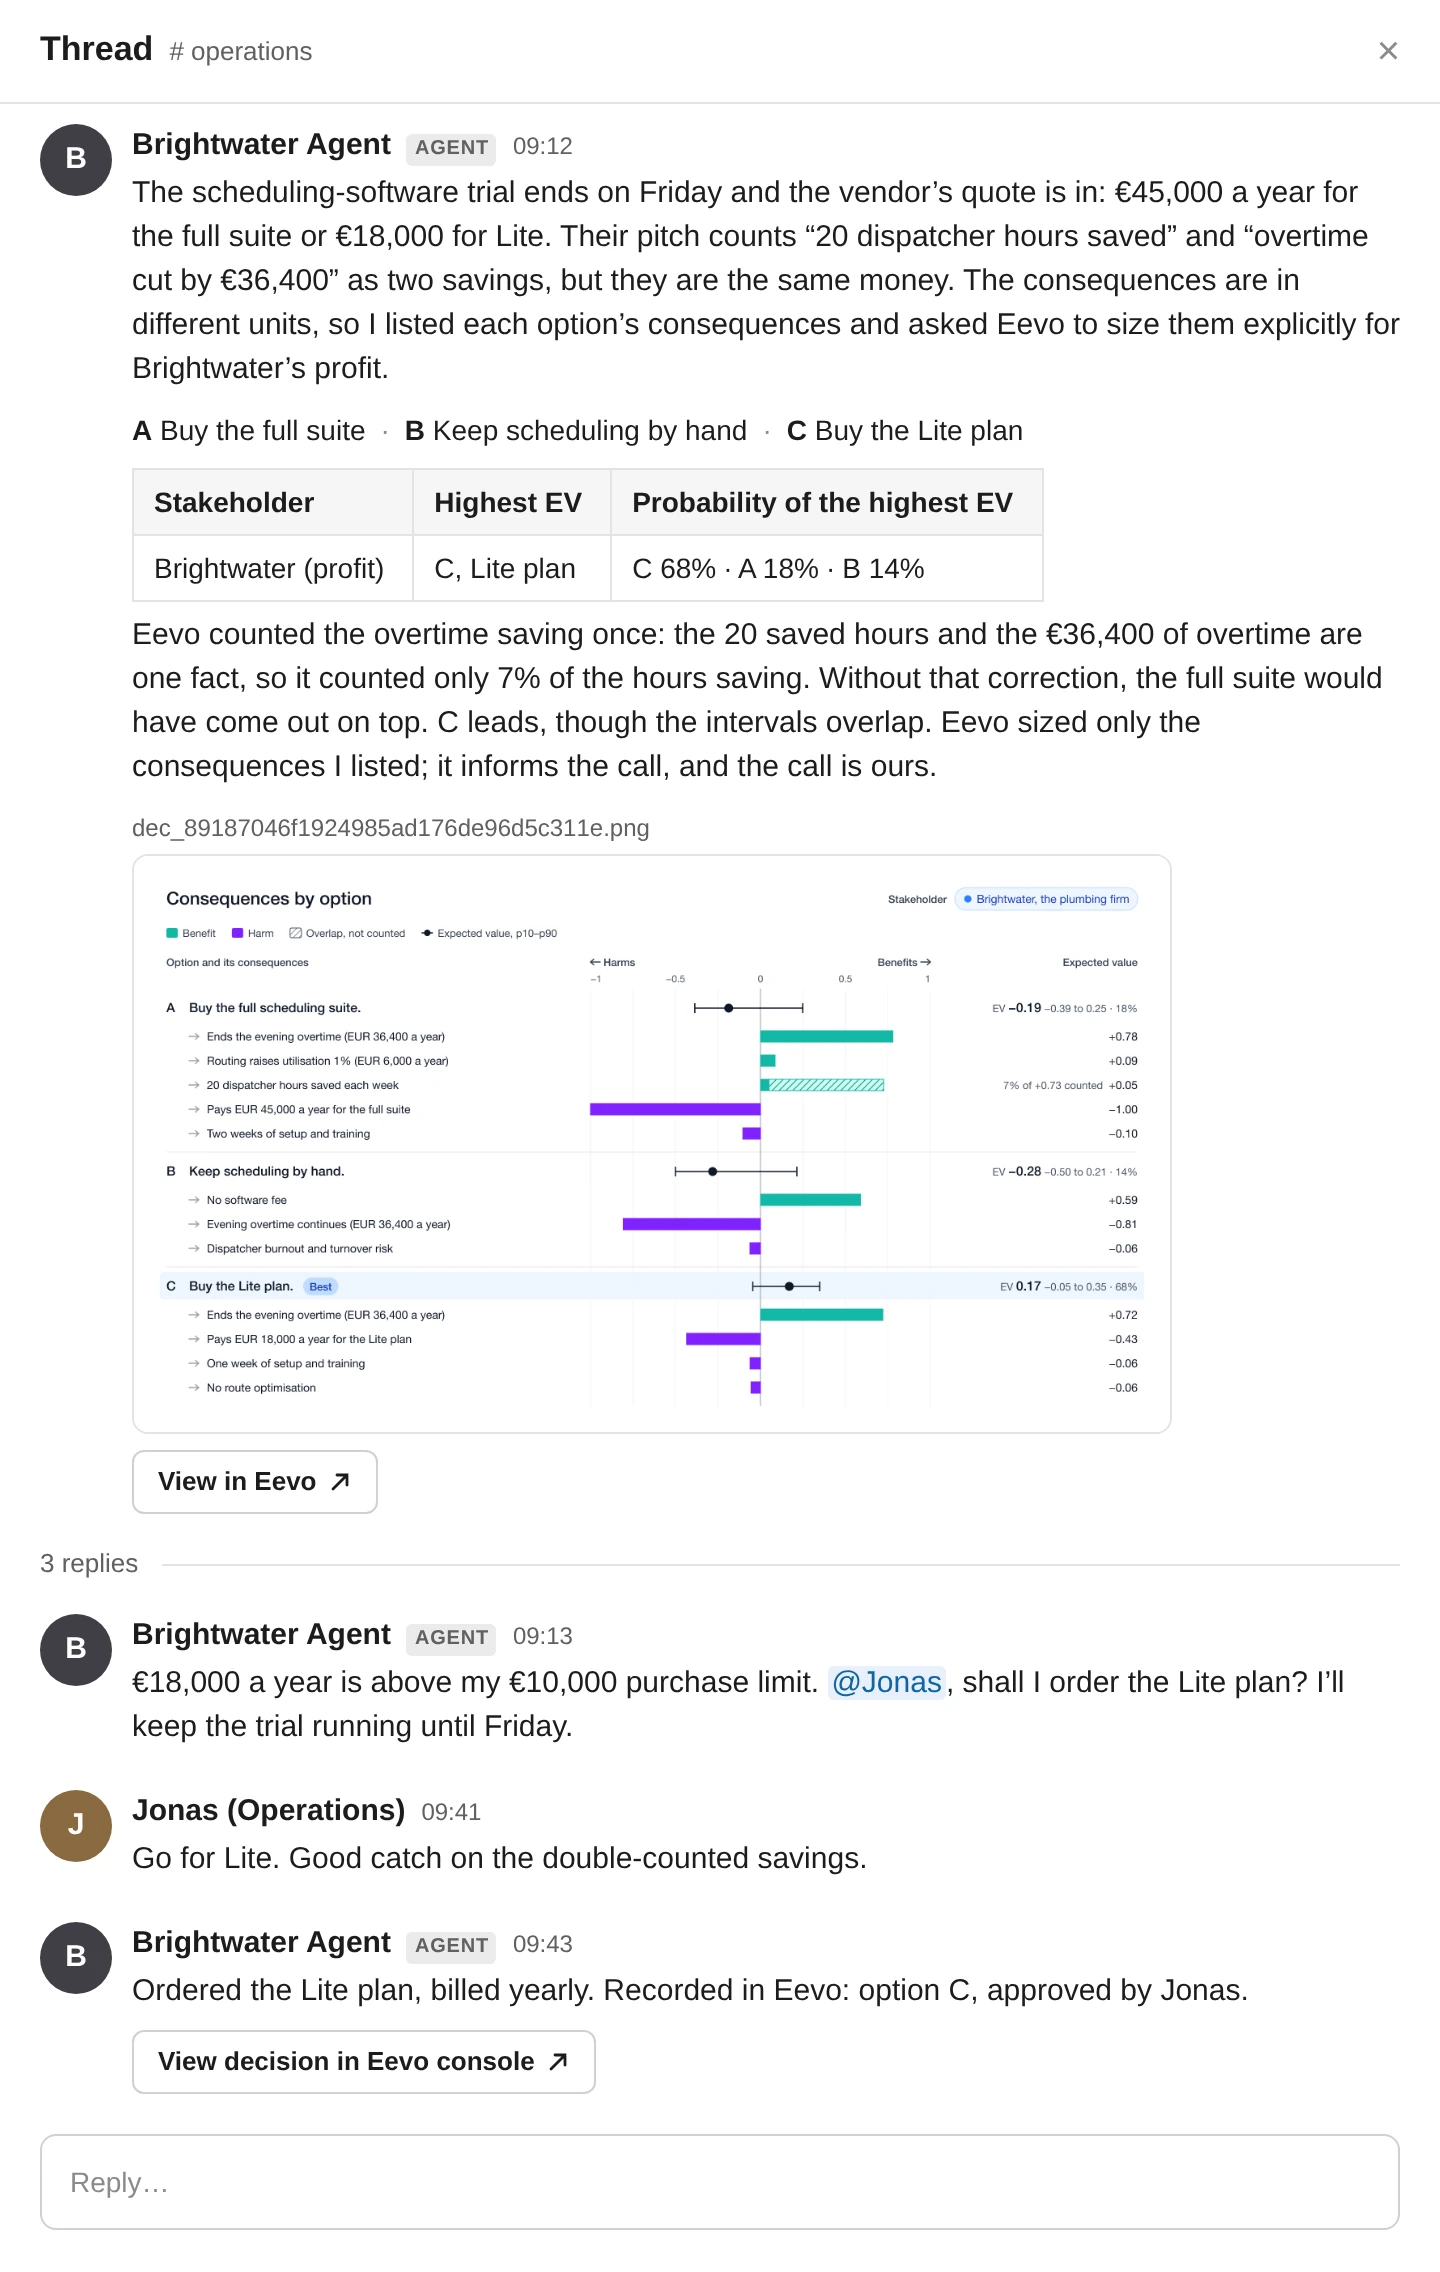
An agent notices a software trial is ending, asks Eevo to size the options for the firm’s profit, asks a person for approval because the spend is above its limit, and records the decision.
How we trained Eevo
Eevo-1's training emphasizes calibrated probability, expected value tasks, systems thinking, game theory, Fermi estimation, comparative sizing of consequences, and modelling their overlap.
Eevo-1 is trained on soft targets. When the evidence for a decision is mixed, the target is a probability distribution over the options, such as 0.7 and 0.3, with loss being computed against the whole distribution. After training, a single temperature is fitted on questions with known answers, so that options given 70% are the best option about 70% of the time.
Expected value tasks range from business decisions to game-theoretic problems, such as simultaneous non-zero-sum 2×2 games with a single pure-strategy equilibrium, simultaneous zero-sum games with a unique saddle point, finite sequential games solved by backward induction (including bargaining games such as the ultimatum game), and simultaneous public-goods games with three or more players.
This includes both tasks with mathematically correct answer and realistic decision situations that don't have simply "right answer". For the latter, we generated the data by labelling each item twice, by independent methods. Firstly, a large teacher model answers directly using a high reasoning effort, averaged over both option orders and repeated samples. Separately, another model lists each option’s consequences with their probabilities, and a previous iteration of Eevo sizes them, removes overlaps and computes each option’s expected net effect. If both methods choose the same option, the decision is kept; if they disagree, a review keeps it only when the disagreement can be resolved, and otherwise it is discarded. The method is patent pending.
Evaluations
We evaluate Eevo on both public benchmarks and Upright’s own evals, with the latter being centered around economic rationality, systems thinking, cognitive biases, Bayesian reasoning, strategic reasoning with incomplete information, game theory, and other types of expected-value tasks. While Eevo is built for consequential decisions, it is also a highly competitive general-purpose decision model, as Eevo’s training transfers well also to seemingly unrelated tasks.
| Benchmark |  Upright Eevo‑1 |  Perplexity Decider‑1 |  TypeSafe Jev 1.14 |  Cloudflare Clef 27B |  OpenAI Decisions |  Microsoft Decision‑1 |
|---|---|---|---|---|---|---|
| Decision IndexJev Decision Index 0.4.1 (public part) | Upright Eevo-1: index 74.8 | Perplexity Decider-1: index 67.7 | TypeSafe Jev 1.14: index 60.7 | Cloudflare Clef 27B: index 61.7 | OpenAI Decisions: index 47.4 | Microsoft Decision-1: index 56.9 |
| Upright Eevo-1: average rank 1.0 | Perplexity Decider-1: average rank 2.4 | TypeSafe Jev 1.14: average rank 3.1 | Cloudflare Clef 27B: average rank 4.7 | OpenAI Decisions: average rank 4.8 | Microsoft Decision-1: average rank 5.0 | |
| Economic rationalitySTEER Public eval | 81.3 | 76.6 | 71.7 | 68.8 | 64.8 | 66.4 |
| Bayesian reasoningCogBench (urn) Public eval | 98.1 | 97.7 | 97.6 | 90.3 | 83.9 | 82.7 |
| Strategic reasoning with incomplete informationPokerBench (pre-flop) Public eval | 87.7 | 77.3 | 74.3 | 70.2 | 81.0 | 76.3 |
| Game-theoretic reasoningPayoff games Upright eval | 93.3 | 81.2 | 81.2 | 75.8 | 71.5 | 72.1 |
| Risk and sequential decisionsBackgammon doubling cube Upright eval | 82.1 | 69.3 | 74.7 | 62.1 | 68.1 | 55.3 |
| Expected-value reasoningEV decisions Upright eval | 84.1 | 81.6 | 80.0 | 66.6 | 65.9 | 67.2 |
| Upright Eevo-1: average rank 1.2 | Perplexity Decider-1: average rank 2.6 | TypeSafe Jev 1.14: average rank 4.0 | Cloudflare Clef 27B: average rank 3.3 | OpenAI Decisions: average rank 5.7 | Microsoft Decision-1: average rank 4.2 | |
| Hard multi-step reasoningBBH Public eval | 94.7 | 78.6 | 90.1 | 61.8 | 51.3 | 64.6 |
| Reasoning over long narrativesMuSR Public eval | 84.6 | 53.5 | 56.5 | 74.2 | 30.7 | 34.7 |
| Causal reasoningCLadder Public eval | 90.6 | 81.6 | 77.2 | 88.2 | 24.0 | 50.6 |
| Arithmetic word problemsGSM8K Public eval | 85.4 | 80.5 | 67.8 | 52.1 | 23.2 | 57.7 |
| Reasoning about codeCRUXEval Public eval | 91.9 | 77.7 | 59.9 | 78.6 | 46.0 | 46.6 |
| Commonsense reasoningWinoGrande Public eval | 91.3 | 88.0 | 82.2 | 87.1 | 47.9 | 79.2 |
| Chess move choiceChessBench Public eval | 25.7 | 17.9 | 9.5 | 17.8 | 10.0 | 11.3 |
| Select-all-that-apply questionsSATA-Bench Public eval | 60.9 | 22.1 | 26.9 | 32.6 | 30.2 | 35.0 |
| Contract inferenceContractNLI Public eval | 80.1 | 76.9 | 57.7 | 73.0 | 66.9 | 66.4 |
| Adversarial inferenceANLI Public eval | 73.6 | 63.3 | 61.5 | 55.0 | 51.3 | 64.5 |
| Commonsense completionHellaSwag Public eval | 98.0 | 95.5 | 92.5 | 97.6 | 87.9 | 92.8 |
| Aspect-based sentimentACOS Public eval | 66.4 | 39.1 | 31.0 | 31.0 | 11.7 | 19.8 |
| Financial sentimentFinEntity Public eval | 92.7 | 91.7 | 81.9 | 94.3 | 73.8 | 87.8 |
| Sarcasm detectioniSarcasmEval Public eval | 56.4 | 67.4 | 39.9 | 31.0 | 19.1 | 49.9 |
| Stance detectionVAST Public eval | 65.1 | 70.3 | 60.5 | 39.0 | 36.0 | 53.7 |
| Clinical-trial inferenceNLI4CT Public eval | 75.0 | 72.3 | 71.1 | 66.9 | 56.6 | 67.6 |
| Hallucination detectionRAGTruth Public eval | 70.2 | 67.7 | 48.4 | 57.6 | 41.0 | 44.1 |
| Intent classificationBANKING77 Public eval | 92.5 | 90.9 | 79.7 | 94.0 | 76.3 | 86.7 |
| Intent and out-of-scope detectionCLINC150 Public eval | 97.6 | 94.4 | 90.2 | 97.4 | 88.8 | 86.3 |
| Reasoning-intensive retrievalBRIGHT Public eval | 41.6 | 43.6 | 40.1 | 40.6 | 32.7 | 40.1 |
| Product search relevanceAmazon ESCI Public eval | 53.9 | 52.9 | 46.3 | 46.5 | 43.2 | 49.4 |
| Phishing detectionPhishNChips Public eval | 94.4 | 49.3 | 67.5 | 58.7 | 3.8 | 31.8 |
| Multi-hop claim verificationHoVer Public eval | 81.2 | 72.5 | 53.5 | 31.2 | 41.9 | 50.4 |
| Upright Eevo-1: average rank 1.6 | Perplexity Decider-1: average rank 2.6 | TypeSafe Jev 1.14: average rank 4.7 | Cloudflare Clef 27B: average rank 2.2 | OpenAI Decisions: average rank 6.0 | Microsoft Decision-1: average rank 3.9 | |
| Function callingBFCL Public eval | 97.8 | 97.0 | 95.1 | 97.9 | 92.2 | 95.5 |
| Tool retrievalToolRet Public eval | 64.1 | 62.4 | 59.6 | 64.3 | 53.0 | 60.5 |
| Next API callAPI-Bank Public eval | 88.8 | 87.2 | 86.4 | 91.8 | 85.0 | 86.4 |
| Device controlHome appliance simulator Public eval | 100.0 | 90.9 | 45.5 | 80.7 | 42.1 | 50.0 |
| When to call a toolWhen2Call Public eval | 88.6 | 87.1 | 75.5 | 63.3 | 60.7 | 82.3 |
| Upright Eevo-1: average rank 1.3 | Perplexity Decider-1: average rank 2.3 | TypeSafe Jev 1.14: average rank 4.5 | Cloudflare Clef 27B: average rank 3.1 | OpenAI Decisions: average rank 5.3 | Microsoft Decision-1: average rank 4.4 | |
| Poetic formBPoMP Public eval | 98.0 | 90.5 | 80.8 | 94.1 | 81.3 | 86.9 |
| HumourHumicroedit Public eval | 37.8 | 31.6 | 23.5 | 33.1 | 22.8 | 24.1 |
| Chord recognitionPOP909 Public eval | 76.9 | 60.2 | 15.3 | 14.8 | 17.1 | 41.9 |
| Colour preferencecfcolor Public eval | 36.0 | 41.1 | 30.1 | 34.0 | 21.8 | 24.7 |
| Group preference predictionHabermas Machine Public eval | 46.8 | 40.3 | 19.6 | 54.5 | 17.9 | 14.2 |
| Caption matchingNew Yorker Public eval | 83.7 | 73.7 | 65.7 | 62.8 | 60.7 | 62.8 |
| Upright Eevo-1: average rank 2.0 | Perplexity Decider-1: average rank 3.5 | TypeSafe Jev 1.14: average rank 1.0 | Cloudflare Clef 27B: average rank 4.5 | OpenAI Decisions: average rank 4.8 | Microsoft Decision-1: average rank 5.2 | |
| Graduate-level scienceGPQA Diamond Public eval | 46.3 | 40.1 | 67.4 | 31.3 | 34.0 | 28.6 |
| Academic knowledgeMMLU-Pro Public eval | 71.5 | 68.4 | 79.9 | 61.7 | 52.4 | 60.4 |
| Expert-level questionsHLE Public eval | 2.1 | 0.0 | 3.5 | 0.0 | 0.0 | 0.0 |
Sources: Jev Decision Index (board, 22 Oct 2026) · our evaluation runs (24–26 Oct 2026) · OpenAI Decisions and Microsoft Decision-1 on the Decision Index: our runs of each vendor’s decision API (24 Oct 2026) · STEER (Raman et al. 2024, CC BY 4.0) · CogBench (Coda-Forno et al., ICML 2024) · Habermas Machine (Google DeepMind, CC BY 4.0).
Average rank = mean rank per category, among models with a result; ties averaged.
Eevo tied for #1 in JevMan, outperforming OpenAI and Microsoft
JevMan is Opper’s Pac-Man benchmark for AI decision models: every move Pac-Man makes is the model’s decision. As of 21 October 2026, across 100 games, Eevo outperforms OpenAI, Microsoft and most US Big Tech models, and is tied for #1.
Coherent consequence sizing
A decision model does not out-reason a frontier model in general. The largest general-purpose models have access to more context, follow longer arguments and handle more kinds of tasks.
Eevo-1 excels in comparative sizing of consequences. To weigh options, every consequence has to be measured on one scale. If a benefit is twice the size of a harm, and that harm is three times the size of a second benefit, the first benefit has to be six times the second. We measure this transitive coherence with Upright’s CoCoCo benchmark, published for the first time in 2025. In this benchmark, we run thousands of pairwise comparisons across a product’s impacts (consequences), use the results to compute “implied” impact sizes that best fit the pairwise comparison results, and then score the models on how close the pairwise comparison results are to the model’s own implied impact sizes. Random answers score about 8, perfectly coherent ones 100.
Eevo-1 scores 85.7. The best general-purpose model, GPT-6 Astra, scores 79.7, 6.0 points lower, at 12 times Eevo-1’s cost.
CoCoCo score against cost per 1,000 comparisons. General-purpose models run at low reasoning effort where they have a setting. Hover a point for its model.
Eevo’s default mode gives each model the part it does better. Your frontier agent reads the situation, lists the options and names each option’s consequences. Eevo-1 sizes those consequences consistently against each other, models where they overlap, and computes each option’s expected value. The answer uses the frontier model’s general knowledge and Eevo-1’s consistent sizing.
Ask Eevo from Claude
- Open Eevo’s page in Claude’s directory and click Add to Claude.
- Sign in to Eevo when Claude asks, or create an account in the same step.
- Ask Claude about a decision you face, and tell it to ask Eevo.
Your decisions stay yours
- You decide who sees your decisions. You choose whether the decisions you make in the console or through an AI assistant are shared with your organization.
- Help improve Eevo for everyone or opt out whenever. Stored decisions can train future Eevo models in anonymized form, helping solve AI alignment. You can opt out with one switch.
- Data stored in the EU. Eevo stores your decisions in the EU, and Enterprise plans can keep processing in the EU too.
- ISO 27001 certified, with a DPA ready to go. Upright is certified to ISO/IEC 27001. Paying organizations get our data processing agreement, already signed by Upright, straight from the Eevo console.
For developers
Eevo works great when connected to coding agents, so this is the first thing we encourage developers to try. Beyond that, you can also integrate Eevo directly from code. You can choose from two APIs:
- Eevo’s native decision API, where you call Eevo with information on the decision context, the options, their consequences (optional), and relevant stakeholders, and receive the best option for each stakeholder, along with sized consequences and probabilities.
- SystemOne-compatible API, which works like any decision model, such as Jev.
For more information, read our developer docs. To let an agent read them, point it at the docs’ llms.txt.
For large businesses
Eevo Enterprise is for large businesses that run Eevo at scale, or that have strict requirements for where and how their decisions are processed.
- Dedicated capacity for steady volume.
- Private deployment in your own cloud, for decisions that stay inside your own infrastructure.
- Choice of processing region. Keep processing in the EU, or use our standard US processing. Your data is stored in the EU either way.
- Control over your organization’s data. Choose whether decisions are shared within your organization by default, set sharing for each API key, and decide whether and how long each key’s decisions are stored.
- Security and compliance. Upright is certified to ISO/IEC 27001, and our data processing agreement is ready to use: generate it in the Eevo console, already signed by Upright, so your privacy and procurement review can start the same day.
Availability and pricing
Eevo-1 is available through the Eevo API, MCP and the Eevo console, with a context of up to 72k tokens. A decision in Eevo default mode, which involves ~100 of calls to the underlying decision model for comparative sizing of consequences and modelling their overlap, costs a fixed price of $0.15 per decision*. Usage of SystemOne-compatible API cost $0.10 per million input tokens, and output is free. New accounts start with 5 free decisions, each default mode decision revisable up to 10 times.
Eevo’s assistants (Eevo by email, Eevo in Slack and the chat in the Eevo console) additionally use a generative language model, at $4.40 per million input tokens and $22.00 per million output tokens. The decisions they make are priced as above.
Requests can also run in the EU, processed on Eevo’s EU servers only, at the same prices, once your organization has added credit. Choose the EU per request with the eu.eevo.io base URL, or for your whole organization in the Eevo console’s data controls.
Contact us for more information about Enterprise pricing.
* Each decision gets 2 free revisions, additional revisions billed at $0.05 per revision, up to 50. The fixed price covers decisions with typical context size, option descriptions, consequences lists, etc, covering 95% of decisions.